Adroitent

admin

Agentic Operating Systems: Accelerating Enterprise AI from Concept to Production | Adroitent

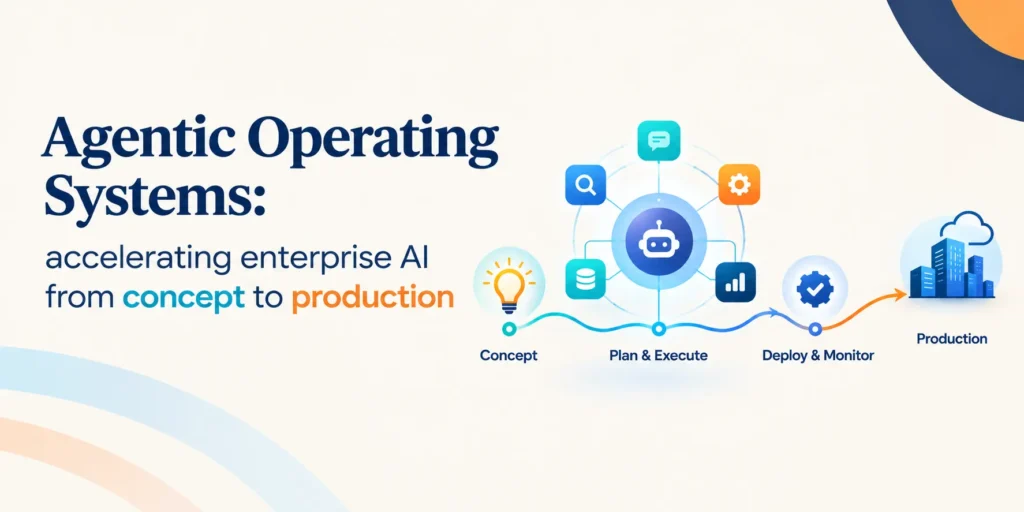
Agentic Operating Systems: Accelerating Enterprise AI from Concept to Production

Agentic Operating Systems for Enterprise AI | Adroitent Home/ Blog/ Agentic Operating Systems Agentic AI · Enterprise AI Agentic Operating Systems: accelerating enterprise AI from concept to production Enterprise AI is evolving from standalone models and copilots to Agentic Operating Systems that reason, collaborate, use enterprise tools, and execute workflows with minimal human intervention. Adroitent InsightsAgentic AIEnterprise AI2 min read Agentic Operating Systems connect AI models, agents, data, applications and governance. At a glance 5 Core building blocks of an Agentic Operating System 7 Enterprise functions where agentic AI can scale 6 Ways DROITai supports production-ready AI The shiftFrom AI Models to Agentic Systems While traditional AI addresses specific tasks, agentic systems combine specialized agents to execute complex business workflows. Realizing this potential requires an integrated architecture connecting AI models, agents, enterprise data, applications, workflows, security, and governance. ArchitectureWhat Powers an Agentic Operating System? Agent orchestration Coordinates multiple agents and workflows. Enterprise integration Connects agents to trusted data, applications, and APIs. Context and memory Enables informed, context-aware decisions. Security and governance Enforces permissions, guardrails, and human oversight. Monitoring and evaluation Tracks reliability, performance, and business outcomes. ProductionFrom Concept to Production Moving beyond AI prototypes requires production-ready engineering, enterprise integration, scalability, and robust governance. Organizations must define agent responsibilities, autonomy levels, safeguards, and continuous evaluation from the outset. This foundation enables enterprises to scale agentic AI across software engineering, customer service, finance, operations, recruitment, sales, and knowledge management. Software engineeringCustomer serviceFinanceOperationsRecruitmentSalesKnowledge management DROITaiPowering Enterprise AI with DROITai The future of enterprise AI lies in combining human expertise with intelligent agents that understand context and execute work. DROITai helps enterprises turn AI concepts into production-ready solutions through AI research, rapid prototyping, agentic AI development, model engineering, enterprise integration, and deployment support. The next phase of enterprise AI is not just about smarter models—it is about intelligent systems that work together to deliver measurable business outcomes. Ready to take AI from concept to production? Talk to Adroitent about agentic AI and how DROITai can help. Talk to our experts More from the blog Keep reading Explore more from Adroitent Contact Talk to our team Read more Stories Customer stories Read more Blog All articles Read more More from Adroitent: all articles · customer stories · adroitent.ai

Agentic Operating Systems: Accelerating Enterprise AI from Concept to Production Read More »

PHP2Shell remediation blog banner featuring a laptop with a PHP2Shell security warning, a protective shield, and repair icon, illustrating the importance of immediate cybersecurity remediation for businesses.

PHP2Shell Remediation: Why Businesses Should Act Immediately

PHP2Shell Remediation: Act Immediately | Adroitent Home/ Blog/ PHP2Shell remediation Security Advisory · PHP PHP2Shell remediation: why businesses should act immediately Two critical PHP flaws let anyone on the internet take over a web server without a password, and attackers were exploiting them before they were public. Adroitent InsightsSecurity AdvisoryPHP2 min read Updating PHP is the only complete fix for the PHP2Shell flaws. At a glance 9.2/10 Severity rating for both PHP flaws 4 days Attack attempt caught before the flaws were public Oct 21 Emergency fixes released by the PHP project 4 Patched PHP branches: 8.5, 8.4, 8.3 and 8.2 Two serious security flaws have been found in PHP, the programming language behind most websites. They’re rated 9.2 out of 10 for severity. They let anyone on the internet take over a web server without a password, and attackers were already trying to exploit them before the flaws were made public. The riskWhy a fix is urgent Attackers are already at work. Amazon’s security systems caught an attack attempt on October 17, four days before the flaws were made public. The NSA has warned that attackers are likely to build tools to exploit them. Real damage is happening. Government and public-sector websites in several countries have gone offline, according to the BBC. No workaround exists. Because the problem is in PHP itself and not in your website or its settings, the only complete fix is to update PHP. The catchWhy it’s harder than it sounds Updating your website software isn’t enough. Updating WordPress, Drupal, or Laravel doesn’t fix this. The underlying PHP engine has to be updated, and the servers restarted so the fix takes effect. You may not know where PHP is hiding. It’s often built into other products, appliances and services, so exposure is easy to miss. Older versions are stuck. PHP versions before 8.2 won’t get an official fix. You’ll need a patch from your vendor or an upgrade to a newer version. A third, smaller flaw (CVE-2026-115560) has only a temporary configuration workaround until PHP’s next regular release. Patching doesn’t clean up an existing break-in. If an attacker already got in, they may have left hidden access or malicious code behind, so systems should also be checked for signs of compromise. The fixPatched PHP versions The PHP project released emergency fixes on October 21, 2026. The patched versions are PHP 8.5.12, 8.4.27, 8.3.36, and 8.2.35, so businesses should move to the latest release on whichever of these branches they use. PHP 8.1 and older no longer get official fixes, so those systems need a patched build from their vendor or an upgrade to a supported version. PHP 8.5.12PHP 8.4.27PHP 8.3.36PHP 8.2.35 StopgapIf you can’t update right away If an immediate update isn’t possible, your IT team can put interim safeguards in place: lifting PHP’s memory limit, switching off its upload-progress feature, and restarting all PHP workers. These steps reduce your exposure, but they are a stopgap rather than a cure. Updating PHP remains the only complete fix and should follow as soon as possible. Updating PHP remains the only complete fix and should follow as soon as possible. Learn more about PHP2Shell remediation and how Adroitent can help. Not sure where PHP is running? Talk to Adroitent about your PHP exposure and how to remediate it. Talk to our experts Explore PHP2Shell remediation Keep reading Explore more from Adroitent PHP2Shell PHP2Shell remediation Read more Stories Customer stories Read more Blog All articles Read more More from Adroitent: PHP2Shell remediation · all articles · customer stories · adroitent.ai

PHP2Shell Remediation: Why Businesses Should Act Immediately Read More »

Application Support & Maintenance for a Leading US Digital Health Provider

Application Support & Maintenance for a Digital Health Provider | Adroitent Home/ Customer Stories/ Support & Sustenance Services Customer Story · Digital Health · Application Support & Maintenance Application Support & Maintenance for a Leading US Digital Health Provider A leading digital health provider combines clinically proven science with sustained human coaching to help prevent and manage lifestyle-related diseases. Adroitent Case FileDigital HealthApplication Support & Maintenance2 min read Its technology platform brings together live video conferencing, intelligent coach-to-member matching, HIPAA-compliant messaging, wearable-device integrations, and an automated insurance claims pipeline—creating an integrated digital health ecosystem with PHI securely managed throughout. The Challenge As the platform scaled rapidly, product engineering had outpaced the maturity of the application support function, creating operational risk and increasing pressure on the engineering team. Growing production support backlog, including unresolved high-severity issues Engineering capacity constrained as product engineers were pulled into day-to-day production support High operational dependency on key individuals, with critical knowledge undocumented and concentrated within a few people Complex technology and integration landscape, spanning multiple applications, databases, automated processes, third-party services, and wearable devices Strict HIPAA and PHI requirements, making every production change and support activity highly controlled and compliance-sensitive Product engineering had outpaced the maturity of the application support function. The Adroitent Solution Adroitent established a structured transition and application support model focused on knowledge capture, operational stability, and progressive ownership rather than simply adding support resources. The transition combined detailed due diligence, structured knowledge transfer, documentation, and hands-on resolution of live production tickets before Adroitent assumed full support ownership. Key Elements of the Solution Blended onsite–offshore support model with dedicated coordinators, backlog and maintenance teams, and built-in backup resources Jira-driven delivery and sprint management, supported by a ticket categorization matrix and clearly defined change-management process Comprehensive application and Oracle database documentation established as a core transition deliverable Multi-level governance framework, spanning daily stand-ups, operational reviews, and quarterly executive governance HIPAA compliance embedded across support processes, access controls, production procedures, and operational governance Structured knowledge management and cross-training to reduce dependency on individual resources and improve support continuity Tools & Technologies Application & DevOps JiraActivatorEclipseGitJenkins Database & Development OracleSQL DeveloperMySQLMongoDB tools Collaboration & Documentation ConfluenceSlack By the numbers 1 Single accountable partner for application support and maintenance 3 Governance levels: daily stand-ups, operational reviews, quarterly executive governance 5 Platform capabilities in one integrated digital health ecosystem 2 Delivery locations in a blended onsite–offshore model Business Outcomes The engagement enabled the customer to transition from a reactive, engineering-dependent support model to a structured, predictable, and scalable application support function. Freed engineering capacity by reducing the product team’s involvement in day-to-day production support Systematically reduced high-severity backlogs and improved issue resolution Established a single accountable partner for application support and maintenance Created a predictable and transparent delivery cadence through structured governance and Jira-based management Ensured service continuity through cross-training and built-in backup resourcing Improved operational control and documentation across the application and data landscape Delivered cost leverage through the offshore support model while maintaining stringent HIPAA controls Good to knowFrequently asked questions What does a structured transition to application support involve? In this engagement it combined detailed due diligence, structured knowledge transfer, documentation and hands-on resolution of live production tickets, so Adroitent could assume full support ownership progressively rather than all at once. How is HIPAA compliance maintained during production support? Compliance is embedded across support processes, access controls, production procedures and operational governance, so every production change and support activity is controlled and compliance-sensitive by design. How do you reduce dependency on key individuals? By capturing knowledge in application and Oracle database documentation, running structured knowledge management and cross-training, and keeping built-in backup resources, so critical knowledge is no longer concentrated in a few people. How does a blended onsite–offshore support model work? It pairs onsite presence with offshore delivery, using dedicated coordinators, backlog and maintenance teams and built-in backup resources, supported by Jira-driven delivery and a defined change-management process. What governance keeps support predictable? A multi-level framework spanning daily stand-ups, operational reviews and quarterly executive governance, combined with Jira-based delivery and sprint management. Make application support predictable without slowing product engineering. One accountable partner, structured governance, and engineers free to build. Start a conversation Explore Support & Sustenance Services Keep reading Related customer stories Software engineering Always-on reliability and data intelligence for an automotive leader Read story Software engineering Powering AI-driven travel experiences with DevOps and AWS Read story Software engineering Modernization of healthcare applications in the US Read story More from Adroitent: all customer stories · insights & blog · adroitent.ai

Application Support & Maintenance for a Leading US Digital Health Provider Read More »

Automated Healthcare Data Integration Platform for a Leading US-based Healthcare Analytics Provider

Home / Customer Stories / Integration Services Customer Story · Healthcare Analytics · Data Integration Automated Healthcare Data Integration Platform for a Leading US-based Healthcare Analytics Provider The customer The customer is a Nebraska-based healthcare analytics company that serves health information exchanges for direct primary care groups and critical access hospitals, providing population health and value-based care insights. Adroitent Case FileHealthcare AnalyticsData Integration · Pentaho on AWS2 min read Major Challenges 01 Fragmented integrations Each hospital had different source systems and integration patterns across RDBMS, NoSQL, cloud, and standalone environments. 02 Diverse data & cadences APIs, HL7/FHIR/CCDA, files, and clinical feeds arrived in different formats and on different schedules. 03 Manual onboarding Every new hospital required fresh source analysis, mapping, and extraction logic, making onboarding slow and unpredictable. 04 No unified patient identity Patient data had to be reliably linked across multiple systems to create a true 360° view. 05 Inconsistent data Formats, data types, and business rules varied by source, requiring standardization before analytics. 06 PHI & compliance Secure connectivity, HIPAA compliance, and appropriate de-identification were mandatory for every data exchange. 07 Manual operations Refreshes depended on people running and watching jobs, with limited logging and exception handling. The customer transformed hospital onboarding from bespoke, development-heavy integrations into a repeatable model with connect, configure, schedule, and go. Solution by Adroitent Adroitent built a metadata-driven, reusable integration platform on Pentaho Data Integration 7.1, deployable in the cloud or on-premise, transforming hospital onboarding from development into configuration. Reusable ETL templates Metadata-driven jobs and transformations accelerated onboarding. Unified data ingestion APIs, flat files, CCDA, and HL7 standardized through a common pipeline. AWS-enabled architecture S3, Lambda, and PostgreSQL powered scalable data movement and warehousing. Built-in automation & controls Scheduling, data quality checks, exception handling, and logging enabled reliable operations. The game changer Production-proven scalability A single parent job automated four claims extracts using metadata-driven file locations with no manual intervention. Metadata-drivenReusable templatesScheduled refreshesBuilt-in quality checks By the numbers 4 Claims extracts automated by a single parent job 5 Data domains unified in one clinical data warehouse 360° Patient view with a consistent patient identity 0 Manual intervention in the automated extracts Business Outcomes Transformed hospital onboarding The customer transformed hospital onboarding from bespoke, development-heavy integrations into a repeatable model with connect, configure, schedule, and go. The team could onboard new hospitals faster, run data refreshes on a predictable cadence, and shift the analytics team’s focus from integration plumbing to delivering insights and business value. Configurable metadata and scheduled setup replaced development-heavy onboarding. Scalable growth Reusable templates enabled new hospitals without proportionally increasing ETL resources. Predictable data freshness Automated, scheduled refreshes replaced manual runs with a reliable data cadence. Unified clinical data warehouse Claims, eligibility, pharmacy, EMR, and biometrics consolidated in PostgreSQL with a consistent patient identity. Greater data trust Built-in quality and consistency checks identified issues before they reached dashboards. Lower operational effort Exception handling, logging, and restart procedures simplified monitoring and troubleshooting. Tools & technology The stack behind it Build Pentaho Data Integration 7.1PostgreSQLAWS S3AWS Lambda Sources & standards HL7FHIRCCDAAPIsFlat files This engagement was delivered as part of Adroitent’s Integration Services practice. Good to know Frequently asked questions What is metadata-driven ETL, and why does it speed up hospital onboarding? In a metadata-driven design, source locations, mappings and rules live in configuration rather than being hard-coded into each job. Reusable templates read that configuration at run time, so adding a new hospital becomes a matter of configuring and scheduling, not building new extraction logic from scratch. What are HL7, FHIR and CCDA, and why do they all need handling? HL7 is a long-established messaging standard for exchanging clinical data. FHIR is its modern, API-friendly successor. CCDA is an XML document format for clinical summaries. Hospitals use a mix of all three, plus flat files and APIs, so a common ingestion pipeline is what keeps downstream data consistent. How is patient identity unified across different hospital systems? Records from claims, eligibility, pharmacy, EMR and biometrics sources are linked so that one person is recognized as one patient across systems. That consistent identity is what makes a true 360-degree patient view possible in the clinical data warehouse. How is PHI protected in an integration pipeline? Protected health information requires secure connectivity, HIPAA-compliant handling and de-identification where appropriate. In this engagement those controls were part of every data exchange, not an afterthought added once data had landed. Can a platform like this run in the cloud or on-premise? Yes. The platform was built to be deployable in either environment. In this engagement it ran on an AWS-enabled architecture using S3, Lambda and PostgreSQL. Onboard faster without rebuilding every time. One metadata-driven platform, one repeatable model, and a data team free to focus on insight. Start a conversationExplore Integration Services Keep reading Related customer stories Software engineeringAlways-on reliability and data intelligence for an automotive leaderRead story → Software engineeringPowering AI-driven travel experiences with DevOps and AWSRead story → Software engineeringModernization of healthcare applications in the USRead story → More from Adroitent: all customer stories · insights & blog

Automated Healthcare Data Integration Platform for a Leading US-based Healthcare Analytics Provider Read More »

The Critical Governance Checklist for Data Leaders Running AI Agents at Scale

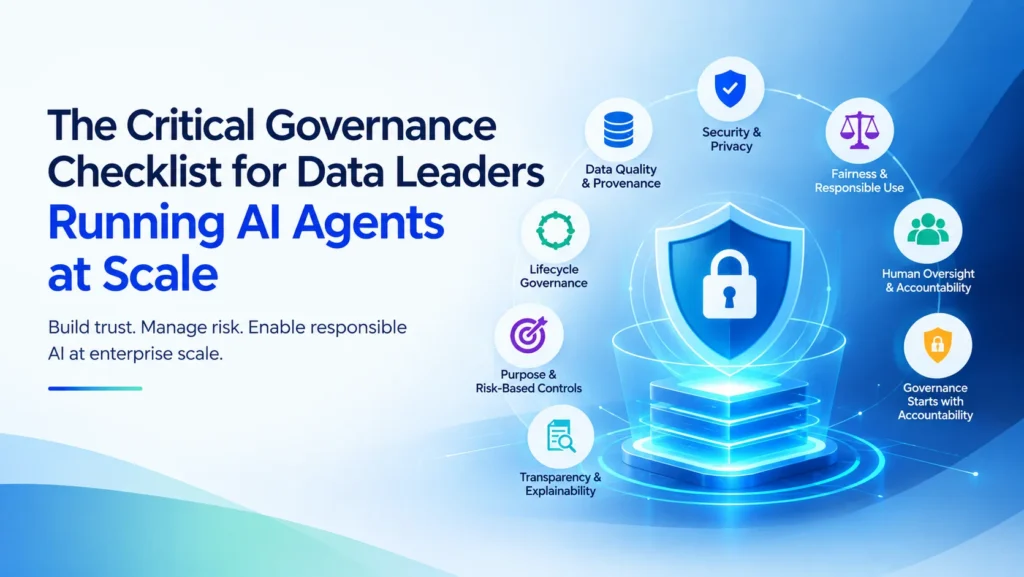
The Critical Governance Checklist for Data Leaders Running AI Agents at Scale

AI Agent Governance Checklist for Data Leaders | Adroitent Home/ Blog/ AI agent governance checklist for data leaders Thought Leadership · AI Governance The critical governance checklist for data leaders running AI agents at scale Enterprises are moving beyond AI pilots to agents that can reason and act. Here are nine governance priorities that let you scale them with confidence. Adroitent InsightsThought LeadershipAI Governance5 min read Key takeaways AI agents don’t just generate insights, they take action, so governance must cover data access, decisions, and unintended actions. Clear ownership, risk-based controls, and a documented purpose for every AI system are the foundation. Data quality, transparency, human oversight, fairness, and security must be built in across the full lifecycle. AI governance is a business strategy shared by business, IT, security, legal, compliance, and operations. The shiftFrom AI pilots to agents that act In 2026, enterprises are moving beyond AI pilots to deploying AI agents that can think, reason, and execute tasks seamlessly. These agents are helping organizations automate workflows, improve customer experiences, accelerate software development, and make faster business decisions. But as AI agents become more autonomous, they introduce a new level of responsibility. Data leaders are no longer just managing data. They are responsible for ensuring AI agents operate securely, responsibly, and in line with business goals. The real challenge is not simply adopting AI; it is creating the governance framework that allows AI to scale with confidence. Why it mattersWhy AI agent governance is different Unlike traditional AI models that generate insights or predictions, AI agents can take action. They can access enterprise data, interact with applications, trigger workflows, and even collaborate with other AI agents to complete complex tasks. That opens up exciting possibilities, and it raises questions every Chief Data Officer, Chief AI Officer, and data leader must answer: How do you ensure AI agents only access the right data? How do you monitor their decisions? How do you prevent unintended actions? How do you stay compliant with evolving regulations? The checklistNine governance priorities every data leader should focus on 1. Governance starts with accountability Clearly define who owns AI, who is accountable for each AI system, who approves its use, and who is responsible for managing AI risks throughout the lifecycle. 2. Risk-based AI governance Not all AI systems need the same controls. Classify systems by intended purpose, potential impact, stakeholders affected, and associated risks, then apply controls proportionate to those risks. 3. AI use must have a defined purpose Every AI system should have a documented business purpose, intended use, users, boundaries, and expected outcomes. AI should not be deployed simply because the technology is available. 4. Govern AI throughout its lifecycle Cover ideation and business approval, design, data preparation, development, validation, deployment, operation, monitoring, change, incident management, and retirement. 5. Data must be fit for purpose Data used by AI should be relevant, accurate, reliable, traceable, and protected, with appropriate controls for privacy and data provenance. 6. Transparency and explainability Provide appropriate information about how AI is used, its limitations, significant assumptions, and how outputs should be interpreted. Explainability should be proportionate to risk and impact. 7. Human accountability and oversight AI should support human accountability, not obscure it. Establish oversight, intervention, review, and escalation mechanisms, particularly where AI can significantly affect people or business outcomes. 8. Fairness and responsible use Identify and manage impacts on fairness, bias, discrimination, safety, privacy, security, accessibility, and other stakeholder concerns, based on the nature and context of the AI system. 9. Security, privacy, and resilience by design Integrate AI governance with existing information security, privacy, cybersecurity, business continuity, and operational risk practices rather than running it as a separate compliance activity. Governance is no longer just about managing data assets. It is about enabling autonomous AI to operate responsibly, transparently, and securely. StrategyAI governance is a business strategy Successful AI governance is not the responsibility of the data team alone. It requires collaboration between business leaders, IT, security, legal, compliance, and operations. Technology platforms provide the technical foundation, but long-term success depends on clear policies, defined ownership, and a culture of responsible AI adoption across the organization. Microsoft FabricDatabricksSnowflakeModern cloud ecosystems How we helpHow Adroitent helps enterprises scale AI responsibly At Adroitent, we believe successful AI initiatives begin with a strong governance foundation. We help enterprises design modern data platforms, implement AI governance frameworks, and deploy AI and Agentic AI solutions that are secure, scalable, and business-focused. We are an ISO/IEC 42001:2023 certified organization, and our expertise spans Data Intelligence, AI Engineering, Cloud Modernization, Data Governance, MLOps, and Responsible AI. By combining technology with proven delivery methodologies, we help organizations accelerate AI adoption without compromising security, compliance, or trust. Final thoughtsGovernance is the foundation for scale AI agents are rapidly becoming an essential part of enterprise operations, and their impact will only continue to grow. As organizations move from experimentation to large-scale deployment, governance becomes the foundation that determines long-term success. Organizations that invest in governance today will be better positioned to innovate faster, earn stakeholder trust, and realize the full value of AI in the years ahead. Good to knowFrequently asked questions What is AI agent governance? AI agent governance is the framework of ownership, policies, controls, and oversight that ensures AI agents operate securely, responsibly, and in line with business goals as they access data, use applications, and take action. How are AI agents different from traditional AI models? Traditional AI models generate insights or predictions. AI agents can take action: they access enterprise data, interact with applications, trigger workflows, and collaborate with other agents to complete complex tasks. That is why they need stronger governance. Who is responsible for AI governance? It is not the data team’s job alone. Effective governance needs business leaders, IT, security, legal, compliance, and operations working together, with clearly defined ownership and accountability for each AI system. Why take a risk-based approach to AI governance? Not every AI system carries the same risk. Classifying systems by purpose, impact,

The Critical Governance Checklist for Data Leaders Running AI Agents at Scale Read More »

Software engineering

From legacy to Lakehouse: the new data strategy for modern enterprises

From Legacy to Lakehouse: The New Data Strategy with Databricks | Adroitent Home/ Blog/ From legacy to Lakehouse Blog · Data & AI From legacy to Lakehouse: the new data strategy for modern enterprises Failed AI initiatives, spiralling infrastructure costs, and data engineers firefighting pipelines instead of building business value all trace back to the same root cause. Here is why the Lakehouse — and Databricks — has become the answer. Adroitent InsightsData & AIDatabricks6 min read Key takeaways Legacy data warehouses were built for reporting on structured data — not for the velocity, volume, and variety that define enterprise data today. Data teams lose up to 70% of their time to brittle pipelines, data reconciliation, and ageing infrastructure. The Databricks Lakehouse unifies storage, governance, processing, and AI through Delta Lake, Unity Catalog, Apache Spark, MLflow, and AutoML. Enterprises that migrate report 30–40% infrastructure cost savings and AI moving from proof-of-concept to production in weeks rather than months. A phased migration — audit, govern, prioritize, run parallel, decommission — is what separates programmes that land from programmes that stall. There is a quiet crisis unfolding inside enterprise data teams worldwide, and its consequences show up everywhere: failed AI initiatives, spiralling infrastructure costs, and data engineers firefighting pipelines instead of building business value. The cause is a legacy data architecture that can no longer support the way modern enterprises need to compete. The solution is the Lakehouse — and Databricks is the platform leading that transformation. As enterprises accelerate their digital transformation journeys, they need a modern data strategy that can unify analytics, data engineering, governance, and AI on a single platform. This is where the Lakehouse architecture, powered by Databricks, is changing the way organizations manage and derive value from their data. The problemThe challenges of legacy data architectures Traditional data warehouses were built primarily for reporting and business intelligence workloads. They create real friction when organizations attempt to scale analytics and AI initiatives. Common challenges include: Data silos spread across multiple systems High infrastructure and licensing costs Complex ETL pipelines that increase latency Limited support for unstructured and semi-structured data Slow access to business insights Difficulty scaling AI and ML workloads As enterprises generate data from cloud applications, IoT devices, customer interactions, and digital platforms, maintaining separate systems for storage, analytics, and AI becomes increasingly inefficient and costly. The diagnosisWhy legacy data infrastructure fails modern enterprises Traditional data warehouses delivered reliable reporting on structured, predictable data, but they were never designed for the velocity and volume that defines enterprise data in 2026. Data teams spend up to 70% of their time managing brittle pipelines, reconciling inconsistent data, and maintaining ageing infrastructure. AI and ML initiatives stall because the governed, accessible data they require is perpetually out of reach. Business leaders wait days for insights that should arrive in minutes. The problem is the architecture — and that is precisely what Databricks solves. By the numbers 70% of data-team time spent maintaining pipelines and infrastructure instead of creating value 30–40% average infrastructure cost reduction after consolidating onto a Lakehouse Hours not days or weeks — the new cycle time for analytics that previously ran in batch Weeks not months — proof-of-concept to production AI on governed, unified data The platformWhat makes Databricks the right platform for Lakehouse migration Databricks’ Lakehouse architecture addresses those challenges by storing data in open object stores like S3, ADLS, or GCS while adding ACID transactions, metadata management, and indexing for reliable analytics. Built on open-source projects including Apache Spark, Delta Lake, and MLflow, the Lakehouse keeps data free from proprietary formats and closed ecosystems. Databricks is not just another cloud data platform. It is the most trusted and most adopted enterprise data and AI platform available today. Databricks introduced the Lakehouse to combine the best capabilities of data lakes and data warehouses into a unified platform. The Databricks Data Intelligence Platform lets organizations store, process, govern, analyze, and apply AI to a single source of truth. Four components do the work: Delta Lake An open-source storage layer that brings ACID transactions, schema enforcement, and versioned data management to cloud storage. Enterprises get the reliability and query performance of a warehouse combined with the flexibility and cost efficiency of a lake, without compromising either. On one platform, teams run SQL analytics, build and deploy machine learning models, process real-time streaming data, and develop generative AI applications — no duplication, no silos. Unity Catalog Enterprise-grade governance built directly into the platform, centralizing data discovery, access control, lineage tracking, and compliance enforcement across every workload and cloud. For enterprises operating across multiple geographies and regulatory environments, compliance becomes an automatic, platform-enforced standard. Apache Spark Processes data at a scale and speed legacy systems cannot approach — accelerating ETL pipelines, reducing processing times from hours to minutes, and enabling real-time analytics. MLflow and AutoML Close the loop between data and AI, giving teams a unified environment to experiment, train, track, and deploy models against the same governed, high-quality data that powers analytics. The result is AI that is faster to build, easier to trust, and simpler to scale. Unlike traditional architectures that require multiple technologies and constant data movement between systems, Databricks provides one integrated environment supporting: Data engineering Data warehousing Real-time analytics Machine learning Generative AI Data governance The roadmapHow to begin your legacy-to-Lakehouse migration A successful Databricks migration is not a single event. It is a structured journey that balances speed with stability. The most effective enterprise migrations follow a phased approach: Audit first. Run a comprehensive data audit to catalog existing sources, pipelines, and quality gaps. Govern before you migrate. Establish a governance framework using Unity Catalog ahead of moving data. Prioritize high-value workloads. Migrate these early to demonstrate ROI quickly. Run in parallel. Keep legacy and Lakehouse environments live together to validate outputs. Decommission progressively. Retire legacy systems as confidence in the new platform grows. The difference between migrations that succeed and migrations that stall is expertise. Certified Databricks engineers with hands-on mastery of

From legacy to Lakehouse: the new data strategy for modern enterprises Read More »

Software engineering

One Embedded Team, Four Live Applications, Zero Quality Drift that

One Embedded Team, Four Live Applications | Adroitent Home/ Customer Stories/ Software Engineering Customer Story · IT Services · Software Engineering One Embedded Team, Four Live Applications, Zero Quality Drift The customer is a leading IT services provider delivering ongoing development and enhancement support to its own portfolio of end customers, spanning travel, logistics and e-commerce. Every project carried its own technology stack, its own release cadence and its own business priorities — and all of them ran at the same time. Adroitent Case FileIT ServicesAgile Delivery · Multi-Application Support4 min read The inflection pointFour codebases, four cadences, one delivery problem The customer needed reliable technical support that would let them seamlessly support their own end customers. That customer base was highly diverse, with multiple concurrent projects running in parallel. Each came with its own technology stack, release cadence and distinct business priorities, requiring a flexible, responsive and deeply collaborative support approach. 01Travel Travel-tracking platform Undergoing a complete rebuild from a legacy codebase carrying performance bottlenecks, response issues and long-term maintainability problems. 02Travel Configurable flight-notification system Designed to deliver highly accurate, rules-driven messaging based on dynamic conditions and individual customer requirements. 03Logistics Dock appointment & scheduling platform Enabling seamless coordination of pick-ups, deliveries and end-to-end supply chain visibility across multiple partners. 04E-commerce High-traffic e-commerce and CMS platform Powering online liquor retail operations in Australia, requiring scalability, reliability and a consistent user experience under load. The customer needed a delivery partner who could act as a true extension of their team — embedded, accountable and capable of driving agile execution across a diverse, evolving application landscape. They required consistent quality across multiple codebases, the flexibility to adapt to changing requirements, and the ability to meet externally committed go-live timelines for ongoing modernization work. The hard part was never building any one application. It was holding four of them to the same standard, at the same time. The interventionOne embedded team, one repeatable framework Adroitent placed a single embedded team across the portfolio and gave it a delivery framework that did not change from application to application. The cadence flexed; the standards did not. An agile model built for shifting priorities Adopted a hybrid Scrum model with daily backlog grooming, so priorities could move between applications without stalling the team Applied three-point estimation at task level, alongside enforced coding standards Ran UAT across every application in the portfolio, not only the ones nearing release Time-boxed modernization, delivered in parallel Each project was scoped end to end, from planning through release, on an agile overlapping-phase timeline Those timelines were built to hold against the customer’s own externally committed go-live dates Governance the customer could see Daily stand-ups kept work synchronized before issues ever reached the customer Weekly management reviews tracked risk, with status visible in JIRA in real time rather than in a periodic report The result was a consistent, auditable view of progress across every work stream The game changer QA discipline that scaled across four codebases Every check-in required a QA test request — no exceptions by application Every change set went through code review before it moved forward Continuous regression testing stayed in place throughout, not just before releases This consistency let one team support four live, unrelated applications without quality drifting on any of them QA per check-inMandatory code reviewContinuous regressionPortfolio-wide UAT By the numbers 4 Live applications supported 1 Embedded delivery team 3 Industries served in parallel 0 Quality drift across codebases The payoffFrom portfolio strain to a reusable model Optimized portfolio delivery Four live applications across different domains were supported by a single embedded team, reducing the need for separate pods, separate governance and separate QA. Improved quality and velocity Concurrent delivery was sustained across all four applications without compromising quality or delivery speed. Reduced maintenance burden Reliability issues and accumulated technical debt were addressed, creating a scalable and sustainable foundation across the portfolio. Enabled platform modernization Modernization was delivered on time, reducing migration risk and protecting business continuity. Created a reusable delivery model A repeatable framework covering grooming, code review, regression testing and JIRA visibility now extends to future engagements. The stack behind itTools & technology Build .NETMVC patternSQL Delivery & governance TFS — code repositoryJIRA — requirements & acceptance criteriaConfluence — user stories & project docsVisio — design This engagement was delivered as part of Adroitent’s Software Engineering Services practice. Good to knowFrequently asked questions What is an embedded delivery team, and how does it differ from staff augmentation? An embedded delivery team operates as an extension of the customer’s own organization, owning outcomes across planning, build, QA and release rather than filling individual seats. Staff augmentation supplies people who work under the customer’s process and management. An embedded team brings its own delivery framework, governance and accountability, which is what makes it viable to support several unrelated applications at once. How do you maintain consistent quality across multiple concurrent applications? Consistency comes from making quality gates mandatory rather than release-dependent. Every check-in raises a QA test request, every change set passes code review before it moves forward, and regression testing runs continuously instead of only ahead of a release. Because the same gates apply to every codebase, quality does not depend on which application a developer happened to be working in that week. What is a hybrid Scrum model with daily backlog grooming? A hybrid Scrum model keeps Scrum’s sprint cadence, ceremonies and estimation while borrowing continuous-flow practices for work that cannot wait for the next sprint boundary. Grooming the backlog daily rather than once per sprint lets priorities shift between applications without stalling a team, which matters when several customers set their own release cadences. What is three-point estimation and why apply it at task level? Three-point estimation captures an optimistic, most-likely and pessimistic figure for each item and derives a weighted estimate from the three. Applying it at task level rather than story level exposes uncertainty early and produces forecasts reliable enough to commit to externally, which is essential when go-live

One Embedded Team, Four Live Applications, Zero Quality Drift that Read More »

Top 5 Databricks Use Cases for GCCs in 2026

Top 5 Databricks Use Cases for GCCs in 2026 Home/ Blog/ Top 5 Databricks Use Cases for GCCs in 2026 Insights · Data & AI Top 5 Databricks Use Cases for GCCs in 2026 From unified data platforms to AI implementation at scale — here’s how Global Capability Centers are leveraging Databricks to drive transformation and deliver measurable business outcomes. Adroitent InsightsData & AIDatabricks8 min read Key takeaways Databricks has become the foundational platform for GCCs managing massive data volumes, complex multi-cloud environments, and aggressive AI roadmaps. Unified data platforms on Databricks Lakehouse deliver 40% reduction in infrastructure costs and 60% reduction in data reconciliation time. Real-time analytics enables GCCs to detect operational anomalies quickly with 80%+ reduction in end-to-end latencies. MLflow and Mosaic AI accelerate AI/ML implementation from months to weeks with governed, production-grade deployments. Unity Catalog transforms regulatory compliance from manual effort into automated platform capability. Global Capability Centers (GCCs) have undergone a fundamental transformation, evolving into strategic innovation hubs that drive digital transformation by adopting AI and data-driven decision-making for their parent organizations. This evolution has created a critical requirement for data and AI platforms powerful enough to keep pace with the global growth of GCCs. In 2026, Databricks has become the leading platform, with over 10,000 enterprise customers globally, including Fortune 500 companies. For GCCs managing massive data volumes, complex multi-cloud environments, and aggressive AI roadmaps, Databricks will be the basic foundation for empowering them to stay competitive in the AI world. Here are the five impactful use cases GCCs are deploying on Databricks and the outcomes they are delivering. Use Case 1Unified Data Platform Replacing Fragmented Legacy Stacks The GCC Challenge Most GCCs inherited a fragmented data landscape from their parent organizations with multiple data warehouses, disconnected data lakes, overlapping BI tools, and siloed databases spread across business units and geographies. Data engineers spend most of their time reconciling inconsistencies between systems rather than building intelligence. A single business question such as “What is our global revenue by product line this quarter?” can require pulling data from multiple systems, none of which agree with the other. The Databricks Solution Databricks Lakehouse consolidates the entire data stack onto a single, unified platform. Delta Lake provides a reliable and ACID-compliant storage foundation. Unity Catalog delivers centralized governance such that GCCs can manage data discovery, access control, lineage, and compliance across teams and every cloud. Thus, GCCs get a single source of truth that every team across geographies can access, trust, and query simultaneously. The GCC Outcome GCCs that have unified their data stack on Databricks report a 40% reduction in data infrastructure costs, a 60% reduction in time spent on data reconciliation, and the elimination of shadow spreadsheets and conflicting reports. More importantly, they build a foundation that every subsequent AI and analytics initiative can stand on without rebuilding from scratch. According to Business Wire, Databricks Lakehouse customers found that the solution delivered an average ROI of 482 percent over three years, with an average annual benefit of $30.5M and a payback period of 4.1 months. Use Case 2Real-Time Analytics for Global Operations The GCC Challenge GCCs support parent organization operations across multiple time zones, markets, and business functions simultaneously. Supply chain disruptions, customer service escalations, fraud occurrences, and operational anomalies might occur at any time. Yet, most GCCs still rely on batch-processed analytics that deliver old data; there still exists a lag that translates directly into missed opportunities and undetected risks. The Databricks Solution Databricks structured streaming enables GCCs to ingest, process, and analyze data in real time from IoT sensors, application streams, transaction logs, social media feeds, and API pipelines, all enabled at enterprise scale. Delta Live Tables automates the construction and monitoring of real-time data pipelines, ensuring data quality at every stage of the stream without human intervention. The GCC Outcome GCCs running real-time analytics on Databricks detect operational anomalies quickly and achieve an 80%+ reduction in end-to-end latencies. They deliver real-time dashboards that give parent organization leadership effective real-time visibility into global performance. This replaces static weekly reports with dynamic, real-time intelligence that drives informed decision-making. Use Case 3AI and Machine Learning Implementation at Enterprise Scale The GCC Challenge AI and ML have moved from competitive differentiator to table stakes for GCCs in 2026. Parent organizations expect their GCCs to deliver predictive models, demand forecasting systems, and GenAI applications that transform business processes. Yet most GCC teams struggle with the same recurring obstacles of fragmented, ungoverned, low-quality data that make building reliable, production-grade AI models difficult and slow. The Databricks Solution Databricks provides a unified environment for the AI and ML lifecycle, from data preparation and feature engineering to model training, tracking, deployment, and monitoring. MLflow, natively integrated into Databricks, gives a single platform to track experiments, compare, manage, and deploy models to production with full lineage and reproducibility. Databricks AutoML accelerates the path from data to deployed model, automatically generating baseline models that teams can build on rather than starting from scratch. For GenAI, Databricks Mosaic AI provides the infrastructure to fine-tune, evaluate, and deploy large language models on enterprise data with the governance and security that regulated industries demand. The GCC Outcome GCCs adopting Databricks reduce model development cycles from months to weeks and move AI initiatives from POC to production deployment at scale. They build a governed AI platform that parent organizations trust enough to embed in customer-facing and business-critical workflows. This delivers the AI-driven value that elevates the GCC’s strategic position globally. Use Case 4Data-Driven Talent Intelligence and Workforce Analytics The GCC Challenge GCCs are fundamentally talent organizations that deliver value to parent companies through people, capability, and professionals across engineering, data science, finance, operations, and technology functions. Yet, workforce decisions such as hiring, upskilling, attrition prediction, and performance management are still made on intuition in most GCCs. HR data sits in one system, performance data in another, skills data in a third, and they lack a unified view of the workforce they are managing. The Databricks Solution

Top 5 Databricks Use Cases for GCCs in 2026 Read More »

Beyond Copilot: What AI-Native Means for Enterprise CTOs

Beyond Copilot: What AI-Native Means for Enterprise CTOs

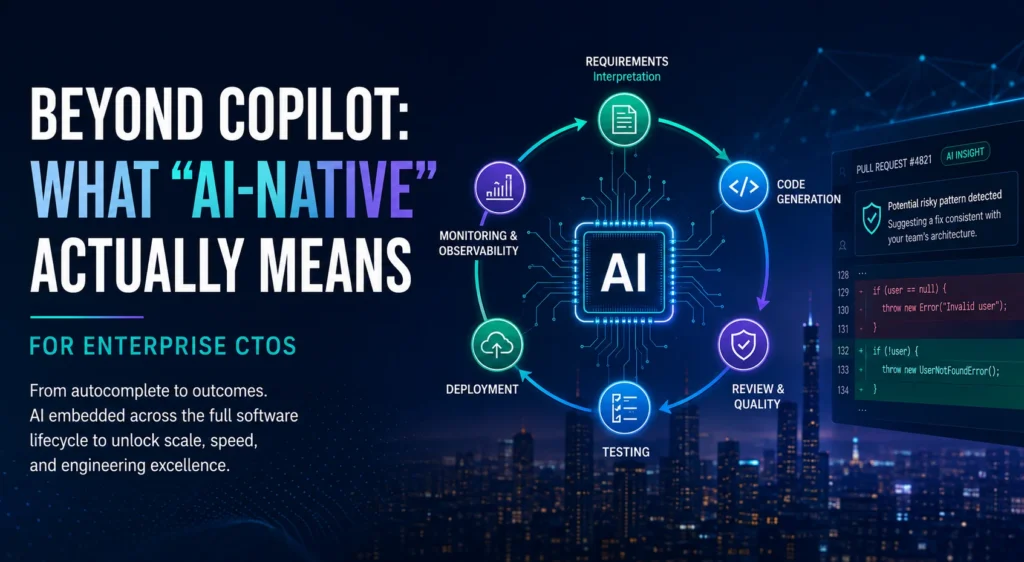
Beyond Copilot: What AI-Native Means for Enterprise CTOs Home/ Blog/ Beyond Copilot: What “AI-Native” Actually Means for Enterprise CTOs Insights · Artificial Intelligence Beyond copilot: what “AI-native” actually means for enterprise CTOs From autocomplete to outcomes. Every enterprise has deployed an AI copilot — but real transformation comes only when AI is embedded across the full software lifecycle, not bolted onto the IDE. Adroitent InsightsArtificial IntelligenceEngineering Leadership6 min read Key takeaways Most enterprise “AI for engineering” stops at autocomplete, delivering only a 10–15% individual productivity bump — far short of the promised transformation. The gap between expectation and outcome isn’t a failure of AI; it’s a failure of scope. AI-native means AI embedded across the full software lifecycle — requirements, code generation, review, testing, deployment, and monitoring — not a smarter autocomplete. At enterprise scale, AI that holds context across the lifecycle is what reduces debt, speeds onboarding, and prevents quality erosion. Every enterprise engineering leader has already deployed some form of AI coding assistant. Adoption isn’t the question anymore; impact is. And when CTOs are asked what has actually changed since rolling out AI copilots, the answers are surprisingly modest: faster autocomplete, fewer keystrokes, maybe a 10–15% bump in individual productivity. Useful, but far short of the transformation that was promised. That gap between expectation and outcome isn’t a failure of AI. It’s a failure of scope. The trapThe autocomplete trap Most “AI for engineering” tools today operate at a single point in the software lifecycle: the moment a developer is typing code. That’s a legitimate use case, but it treats AI as a productivity add-on rather than a structural change to how software gets built. The pattern is familiar by now: AI helps write the function faster, but code review still takes just as long. Integration testing, code-complete criteria, and production readiness are untouched. If AI only touches the moment of writing code, it optimizes a fraction of the software delivery lifecycle — and arguably not the fraction that was ever the biggest bottleneck. The definitionWhat “AI-native” should actually mean An AI-native engineering platform isn’t a smarter autocomplete. It is AI embedded across the full software lifecycle; from requirements interpretation and code generation, through review and testing, to deployment and post-release monitoring. It doesn’t wait to be invoked. It operates as a persistent collaborator, woven into the way the team already works. The distinction matters more than it sounds. A copilot waits to be asked. An AI-native platform proactively flags a risky pattern during code review, suggests a fix consistent with your team’s existing architecture, and learns your codebase’s conventions well enough. Its suggestions significantly reduce review time rather than adding another layer for a human to double-check. That’s the difference between a tool that assists one developer and a system that lifts an entire team’s throughput and quality bar at once. A copilot waits to be asked. An AI-native platform doesn’t wait to be invoked. Let us consider two teams shipping the same feature. On Team A, a developer gets AI-assisted code in minutes — then waits two days for a reviewer to catch a pattern that violates a convention the AI never knew existed. On Team B, the same risky pattern gets flagged before the pull request is even opened, with a fix suggested in the team’s own idiom. Both teams used AI. Only one of them changed how software gets built. The scaleWhy this matters more at enterprise scale For a five-person startup, copilot-level AI might be enough as the codebase is small, the team is co-located, and context lives in people’s heads. Enterprise engineering doesn’t have that luxury. Codebases span thousands of services, teams are distributed across geographies, institutional knowledge decays as people move on, and the cost of a single bad merge compounds across every downstream system. At that scale, AI that only accelerates typing is solving the smallest problem in the room. What actually moves the needle is AI that holds context across the lifecycle: institutional knowledge about why a pattern exists, the ability to catch inconsistency before it ships, and a real reduction in the manual overhead that scales with team size rather than shrinks with it. Closing that gap is exactly the problem platforms like Devailey are built to solve, treating AI not as a plugin bolted onto the IDE, but as infrastructure woven into how engineering organizations operate, from first commit through production support. The questionThe real question for CTOs The question worth asking in your next planning cycle isn’t “which copilot should we standardize on.” It’s this: where in our software lifecycle is AI structurally embedded, and where is it just assisting individual keystrokes? Enterprises that get this distinction right in the next 15 months won’t just ship code faster. They will build engineering organizations that carry less debt, onboard new hires faster, and scale without the quality erosion that has quietly plagued every large codebase long before AI arrived. Thus, moving beyond copilots is about shifting from AI-assisted productivity to AI-driven operations and outcomes for unlocking scale, speed, and smarter decision-making across the organization. Good to knowFrequently asked questions What does “AI-native” mean in software engineering? AI-native means AI is embedded across the full software lifecycle — from requirements interpretation and code generation through review, testing, deployment, and post-release monitoring — rather than acting as a smarter autocomplete. It operates as a persistent collaborator woven into how a team already works, instead of waiting to be invoked. How is an AI-native platform different from a copilot? A copilot waits to be asked and assists one developer at the moment of typing. An AI-native platform proactively flags risky patterns during code review, suggests fixes consistent with the team’s architecture, and learns codebase conventions — reducing review time and lifting an entire team’s throughput and quality, not just individual keystrokes. Why isn’t a coding copilot enough for enterprises? Enterprise codebases span thousands of services with distributed teams and decaying institutional knowledge, where a single bad merge compounds downstream.

Beyond Copilot: What AI-Native Means for Enterprise CTOs Read More »

GCC as a service VS Traditional Captive Model

GCC-as-a-Service vs. Traditional Captive Models

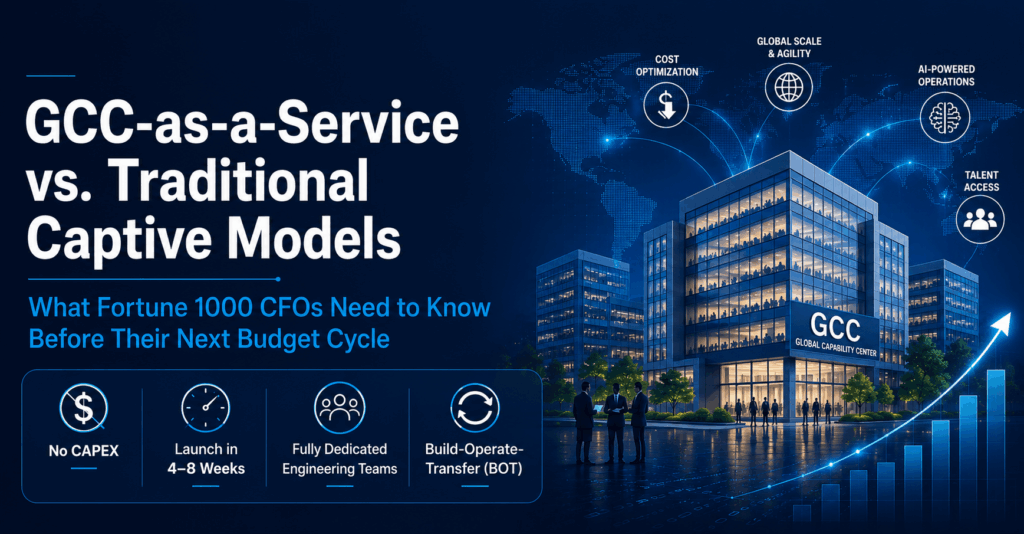
GCC-as-a-Service vs Captive GCC: CFO Guide | Adroitent Home/ Blog/ GCC-as-a-Service vs. captive models: a CFO’s guide Insights · GCC Solutions GCC-as-a-Service vs. traditional captive models: what Fortune 1000 CFOs need to know Every budget cycle, Fortune 1000 CFOs face the same question in a new disguise: build or partner? For two decades the default answer for global capability centers was “build.” In 2026, that may no longer be the smart choice. Adroitent InsightsGCC SolutionsCFO Strategy4 min read Key takeaways Traditional captive GCCs typically take 12–18 months to deliver meaningful output — a direct cost, not just a delay. GCC-as-a-Service shifts spend from CAPEX to a predictable OPEX model and makes teams operational in weeks. Build-Operate-Transfer (BOT) preserves the option to convert to a fully owned captive later. India’s GCC count has grown from ~1,600 to ~2,120, with an estimated 11–12% CAGR in enterprise value projected FY2025–FY2029. Every budget cycle, Fortune 1000 CFOs face the same question in a new disguise: build or partner? For two decades, the default answer for global capability centers was “build” — stand up a captive GCC, hire the leadership team, and treat the multi-year ramp-up as the cost of doing business. That playbook is no longer the safest choice. In 2026, it may not even be the smart one. The hidden taxThe captive model’s hidden tax Traditional captive GCCs are capital-intensive and slow by design. Entity registration, compliance infrastructure, leadership hiring, and operational maturity typically take 12–18 months for a captive center to deliver meaningful output. For CFOs, that delay isn’t just an operational inconvenience — it’s a direct cost. There’s also a governance cost that rarely makes it into the initial business case: once built, captive centers are hard to resize. Downsizing carries reputational, legal, and severance costs. Scaling up means re-running the same slow hiring and infrastructure cycle. The model that promised control often delivers rigidity instead. The model that promised control often delivers rigidity instead. The shiftWhy GCC-as-a-Service changes the calculus GCC-as-a-Service inverts this equation. Instead of building infrastructure, compliance, and leadership from scratch, enterprises plug into an already-operational delivery framework designed for flexible engagement. At Adroitent, we structure this around four GCC enablers: AgileSourcing (four engagement models), Talentalign (our agentic recruitment platform), Devailey (our AI platform for software engineering), and a Build-Operate-Transfer model. Together, these give enterprises full control over every function — while letting them choose exactly how much ownership, control, and timeline they want, without paying the multi-year ramp-up tax of a traditional captive. For a CFO evaluating the next budget cycle, the practical implications are significant: Speed-to-value: Teams can be operational in weeks, not quarters — so AI and digital transformation initiatives don’t have to wait on infrastructure. Capital efficiency: GCC-as-a-Service shifts spend from CAPEX to a predictable, scalable OPEX model, making for a clearer ROI story in board conversations. Optionality: Engagement models like Build-Operate-Transfer (BOT) preserve the option to convert to a fully owned captive later. Built for AI-era delivery: Unlike legacy captive models built around IT staffing, GCC-as-a-Service can be structured from day one around AI-native platforms and agentic delivery — not retrofitted for it years later. Here’s what that looks like in practice: a global manufacturing company expanding into AI engineering needs 300 specialists within six months. Under a traditional captive model, infrastructure and leadership hiring alone could consume more than four months of that timeline. Under GCC-as-a-Service, capability deploys within weeks — ready-to-use infrastructure, niche AI talent, and compliance and legal all managed from day one, while long-term ownership decisions stay flexible. The numbersThe numbers behind the shift The momentum behind India as a GCC hub backs this up. Forbes India reports that the number of GCCs in the country has grown from roughly 1,600 to about 2,120 in recent years, driven by both new centers and expansion of existing ones. Technology and software account for 35% of GCC hiring, with BFSI close behind at 21% — together making up more than half of all hiring as of June 2026. PwC projects India’s GCC sector will keep generating enterprise value at an estimated 11–12% CAGR between FY2025 and FY2029, reinforcing that these centers are increasingly engines of business growth, not just cost centers. The decisionThe decision in front of CFOs this cycle The real debate isn’t “build vs. outsource.” It’s whether this year’s GCC investment should lock into a fixed, multi-year infrastructure commitment — or stay structured for flexibility while capability and AI maturity are still evolving fast. In a year where enterprise AI strategy is being rewritten quarter to quarter, rigidity is an expensive choice, even when it doesn’t show up that way on a single line item. The enterprises that win over the next decade will be the ones that build global innovation capabilities faster than their competitors. GCC-as-a-Service offers a practical path there — combining speed, agility, governance, and access to top talent in a single operating model that’s live from day one. In today’s AI era, competitive advantage belongs to organizations that can innovate continuously. For Fortune 1000 CFOs, GCC-as-a-Service is no longer an alternative delivery model — it’s becoming the fastest route to building future-ready global innovation centers that create sustainable business value. The winners won’t simply build global capability centers; they’ll build them faster, smarter, and with the flexibility to scale as the business evolves. Good to knowFrequently asked questions What is GCC-as-a-Service? GCC-as-a-Service lets an enterprise plug into an already-operational global capability center framework — infrastructure, compliance, leadership and talent — instead of building a captive center from scratch. It offers flexible engagement models so the business chooses how much ownership, control and timeline it wants. How is GCC-as-a-Service different from a traditional captive GCC? A traditional captive GCC is built and owned entirely by the enterprise, typically taking 12–18 months to reach meaningful output and carrying high fixed costs. GCC-as-a-Service is operational in weeks, shifts spend from CAPEX to OPEX, and stays flexible to scale up or down. What is the Build-Operate-Transfer (BOT) model?

GCC-as-a-Service vs. Traditional Captive Models Read More »

DROIT buddy

🟢 Online